
Every model.
One address.
Alnair is an open-source LLM router and AI API gateway. Bring your providers together, set fallback chains, and follow every token from a dashboard that runs on your machine.
Single Rust binary. Embedded dashboard. SQLite storage.
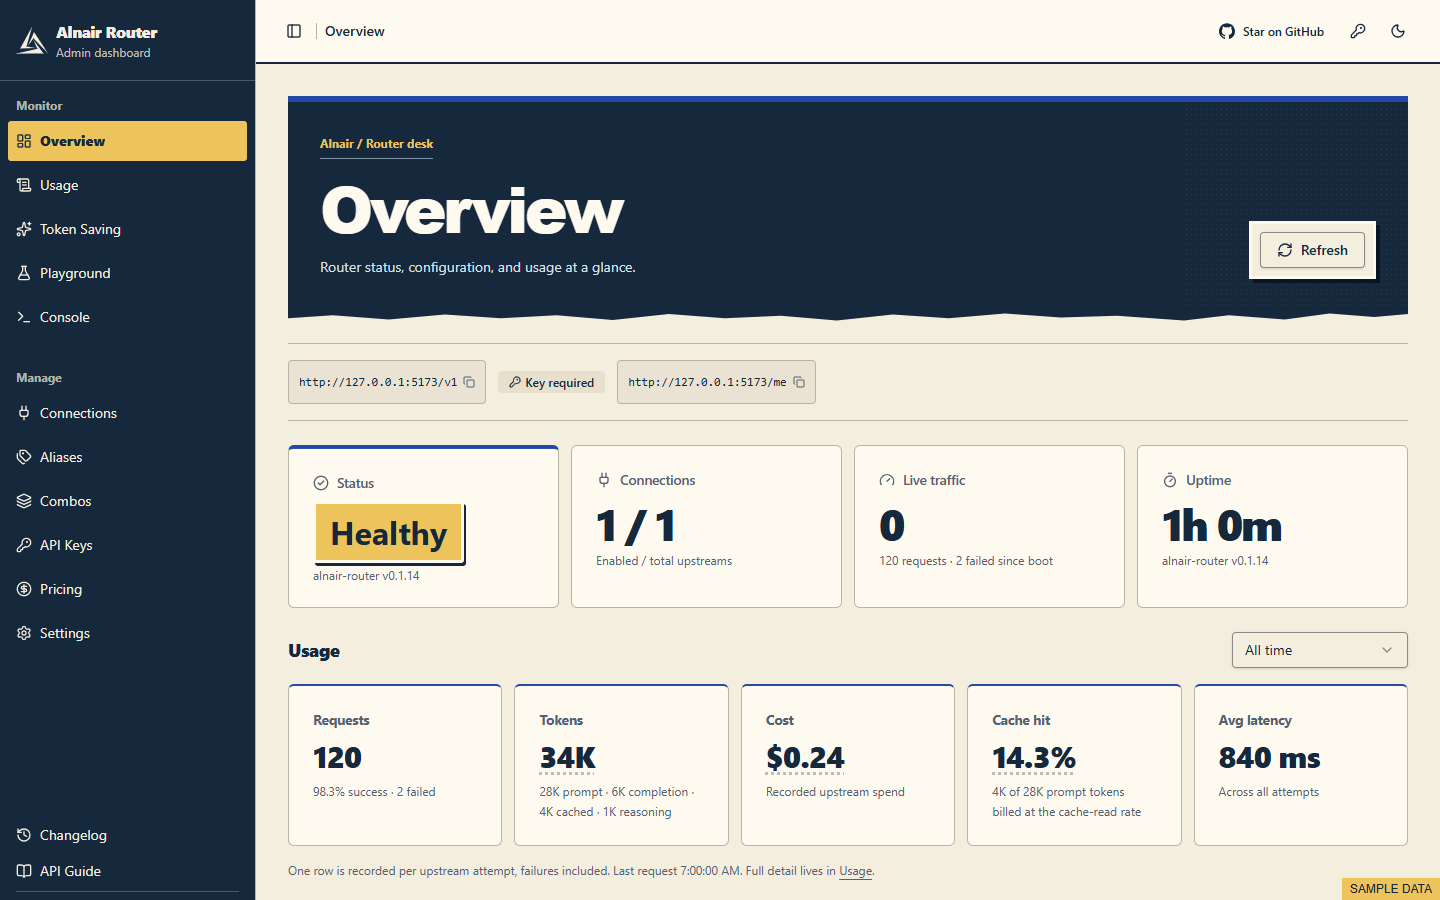
Actual dashboard. Screenshots contain sample data.
01 / The routing desk
Your client keeps its familiar API.
Give your models
a forwarding address.
Point your OpenAI-compatible client at Alnair. A model prefix picks the upstream. A named combo gives you an ordered chain for multi-provider fallback.
Use /v1/chat/completions or
/v1/responses for OpenAI clients, and
/v1/messages for Anthropic clients. Keep your own
provider accounts.
POST /v1/chat/completions
model: "free-forever"
If a tier fails before emitting content, the next tier gets the request. You configure the order.
- Keep keys in check.
- Give client keys rate limits, budgets, model allowlists, and plans.
- Know what ran.
- Inspect requests, token counts, recorded spend, and provider activity.
- Trim bulky context.
- Use the token-saving pipeline to compress tool output and inspect the savings.
02 / A little proof of work
Your usage,
as a sticker.
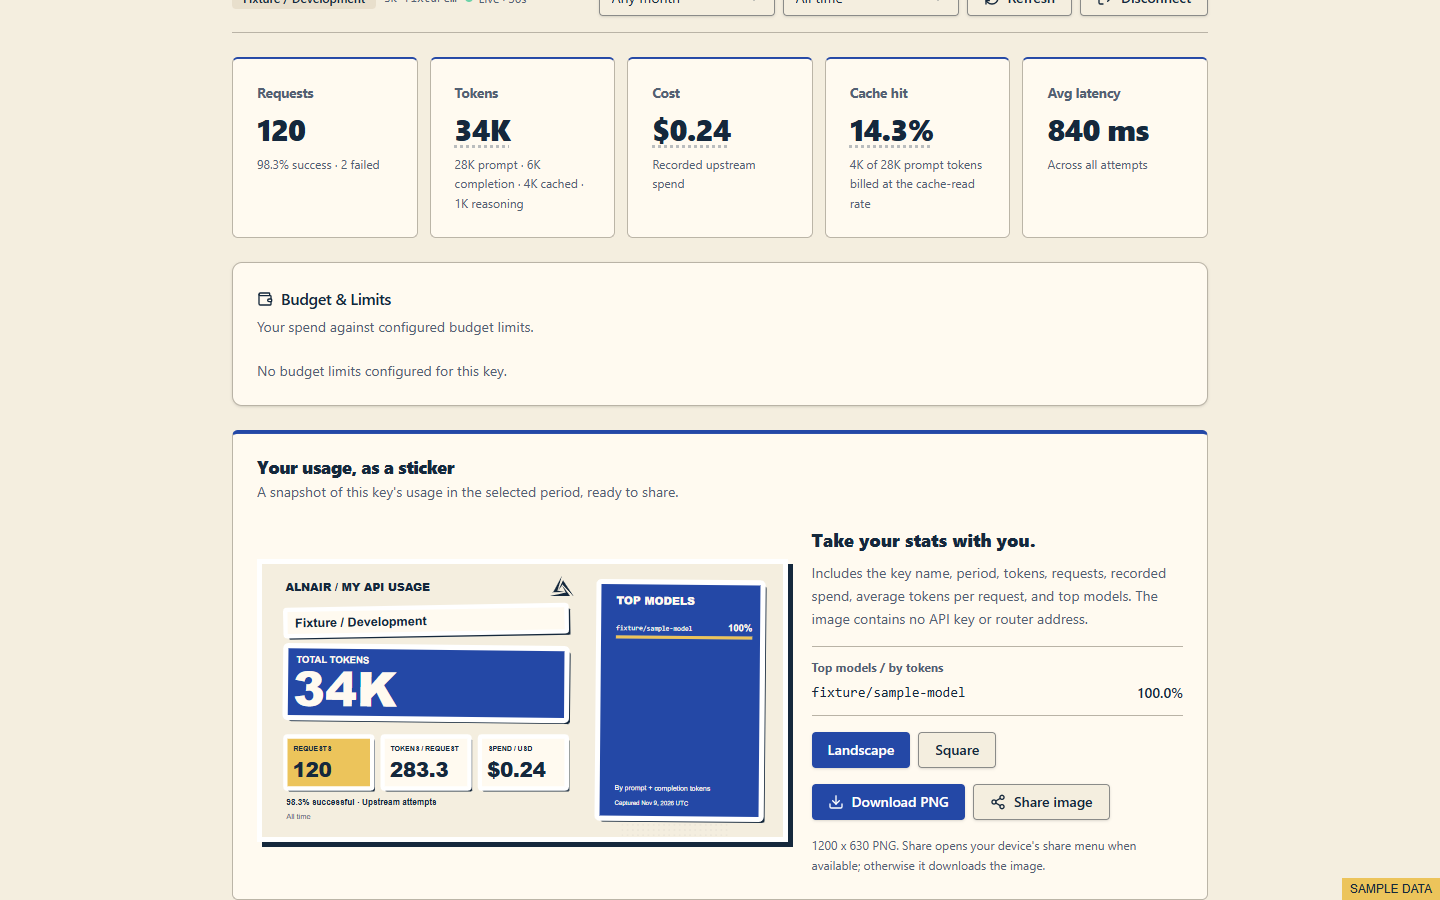
A snapshot worth keeping. Turn your API key's usage into a retro card with total tokens, requests, recorded spend, and your top models.
Download a PNG in landscape or square format. Or open your device's share sheet, where supported.
See more of the dashboardThe exported card leaves out your API key and router address.
03 / Put it on your desk
Your machine.
Your model stack.
Install the router, open the local dashboard, and connect your first provider.
Alnair is MIT licensed. You bring your provider accounts and pay their usage costs.
Download a release binarynpm install -g @xflawlessdev/alnair-router
Run alnair-router start to launch the router. To also
enable auto-start with your session, run
alnair-router install.